Speech-to-text and AI transcription, built into your software
Your users speak to your software, in their own language, in the field as well as at the office. More than transcription: agentic workflows that turn speech into action.
What it does
Speech recognition turns voice into a natural interface for your software. Your users dictate, command, and query, in real time, in their language.
Real-time transcription
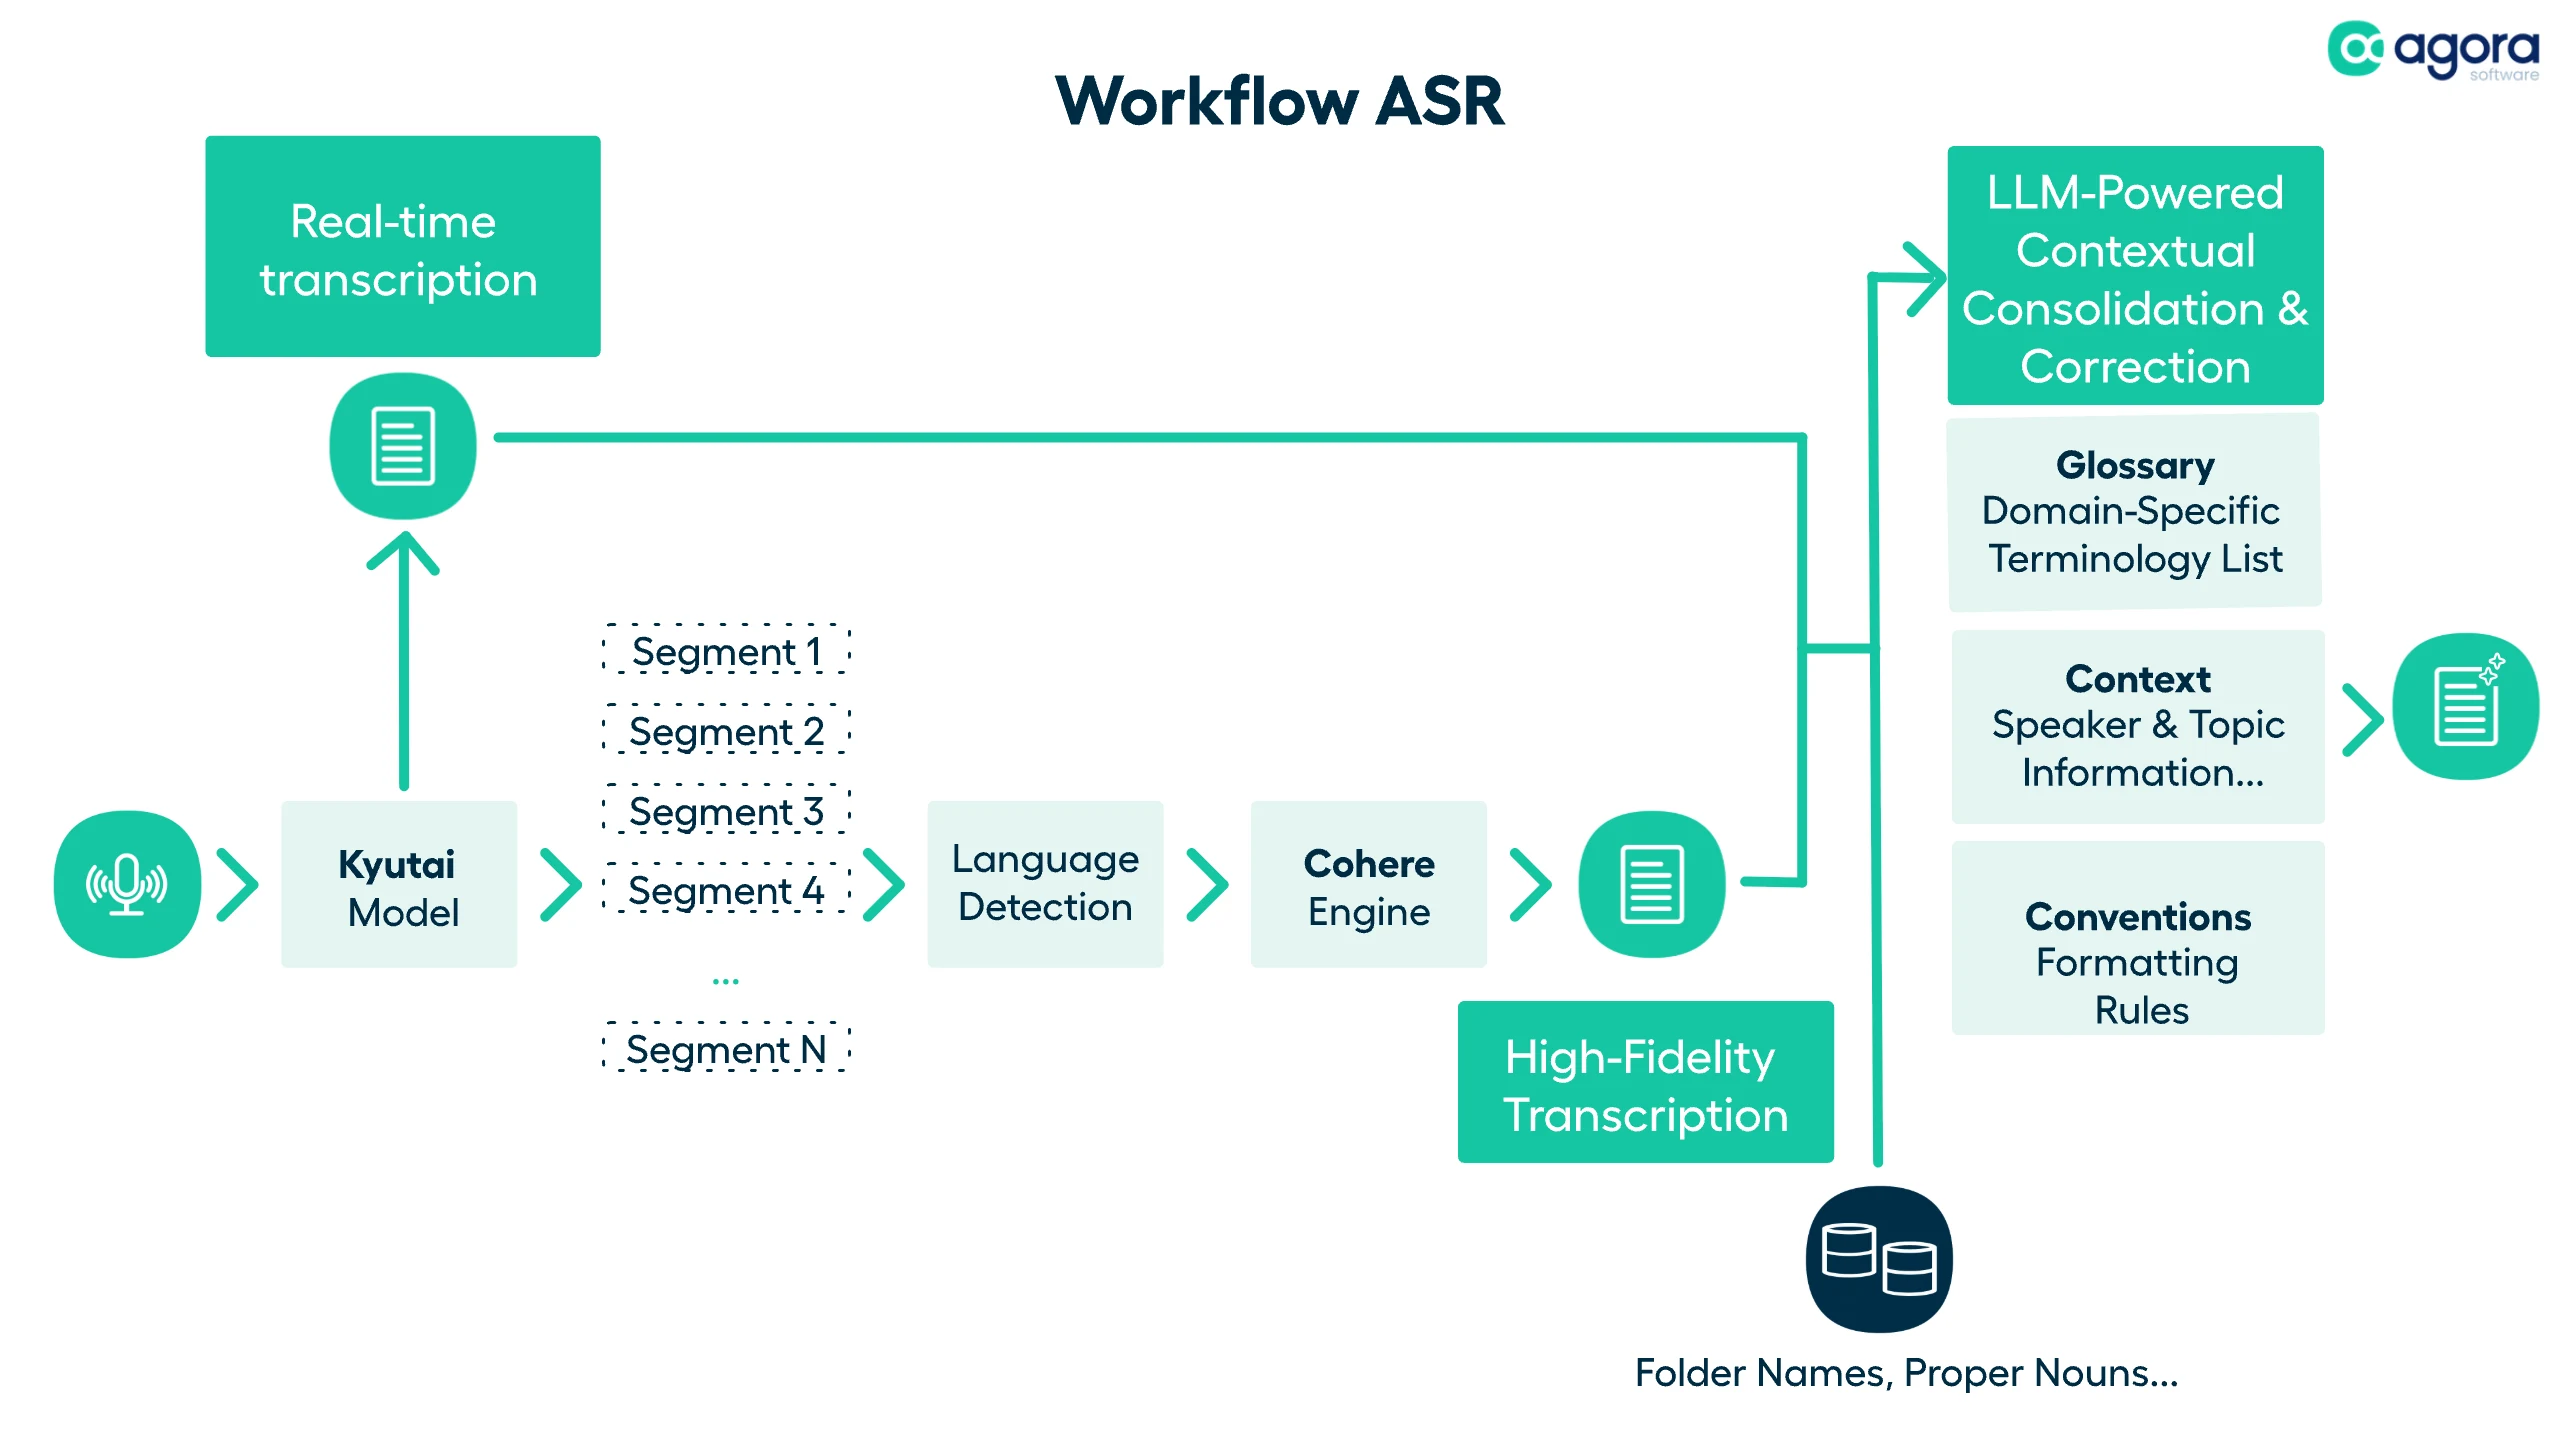
Low-latency streaming transcription. Users see text appear as they speak. The agent receives the text and can trigger actions immediately.
Automatic transcription of recordings
For recordings, meetings or audio documents, audio-to-text transcription runs in batch or asynchronously, when latency is not critical.
Much more than automatic transcription
A sovereign alternative to the Whisper API, hosted in France. The platform is multi-model ASR: we continuously evaluate speech-to-text models and pick, for each language and use case, the one that delivers the best result.
A transcription API gives you text. Agora gives you a result.
Step 1
Transcription
Multi-model ASR: the best model for each language and use case.
Step 2
Context
Your domain vocabulary, your proper nouns, your product codes.
Step 3
Enrichment
An LLM corrects, structures and extracts the useful information.
Step 4
Action
Your software fills in the form, writes the minutes, triggers the next step.
A transcription API stops at step one.
You are tied to no model and no provider: when a better model comes out, your software benefits from it without changing its integration.
Hosted in France • GDPR native • No US cloud dependency • No duration limit • Audio never stored
Agentic workflow around voice
Transcription is just one step. The agent builds a complete workflow around voice capture (in real time or deferred) and can involve an LLM to enrich the result.
Multi-model transcription
A workflow can leverage two ASR models in sequence or in parallel, each more precise on certain aspects, to combine their strengths in a single pipeline.
Contextualisation
Proper nouns, product codes, user's job title, topics covered, domain glossary, user context: contextual information that improves the precision and quality of the result.
LLM post-processing
An LLM steps into the workflow to correct the transcription (typos, formatting), structure it, extract or integrate entities, or generate a summary.
Real-time WebSocket API
Bidirectional audio streaming via WebSocket. Simple integration into any web or mobile application.
 WebSocket API • Real-time streaming • Multi-session
Automatic language detection
Users speak in their language. The system automatically detects which one and seamlessly switches models, with no configuration needed on the user's side.
What can AI transcription do in your software?
Field reports
A technician dictates their service report without putting down their tools, and the software fills in the form.
Automatic meeting minutes
Meetings, interviews, consultations: the recording is transcribed, then structured into minutes by an LLM.
Voice commands
Users ask out loud for what they are looking for, and the agent queries the software to answer them.
Calls and voice messages
Calls are transcribed to extract requests, recurring issues and next steps.
Speech-to-text FAQ
What is the difference between speech-to-text, AI transcription and speech recognition?
All three refer to the same technology: turning speech into text. "Speech-to-text" (or "voice-to-text") is the term developers use most, "AI transcription" focuses on the written result, and "speech recognition" more broadly covers systems that respond to voice, including voice commands. Agora covers all three uses: dictation, transcription of recordings and voice commands.
What does Agora offer beyond a transcription API?
A transcription API turns audio into raw text. Agora builds a workflow around it: transcription takes your domain vocabulary into account, an LLM corrects and structures the result, and an agent puts it to work in your software, such as filling in a form, writing minutes or alerting a team.
Is there a Whisper API alternative hosted in Europe?
Yes. Agora is a sovereign alternative to the Whisper API: the platform is hosted in France, multi-model ASR, and your audio never goes to an external provider. We continuously evaluate speech-to-text models and pick the one that fits your language and use case.
Can meeting minutes be generated automatically?
Yes. The recording is transcribed, then an LLM structures it into minutes: topics covered, decisions, action items. The format adapts to your software and your document templates.
Real-time or deferred transcription: which should I choose?
Real time fits when the user expects an immediate response: dictation, voice commands, live captions. Deferred processing fits long recordings (meetings, interviews, calls), when accuracy matters more than latency. The platform offers both, and a single workflow can combine them.
Which languages are supported?
The main European and Asian languages, including French, English, German, Spanish, Italian, Arabic, Japanese and Chinese. The language is detected automatically, with no setting on the user's side.
Are audio recordings kept?
No. Audio is processed and then deleted, it is never stored. The platform is hosted in France, GDPR compliant, with no external provider.